What it is
Dendrite solves a fundamental bottleneck in agentic AI: the cost of exploring multiple reasoning paths. Current inference engines like vLLM and SGLang are optimized for linear generation, but agents need to branch, backtrack, and explore alternatives.
The Problem
Tree-structured reasoning (MCTS, beam search, speculative decoding) requires forking inference state. In existing engines, forking a 32K context requires copying gigabytes of KV cache, taking milliseconds and consuming massive memory. This makes sophisticated search strategies impractical.
The Solution
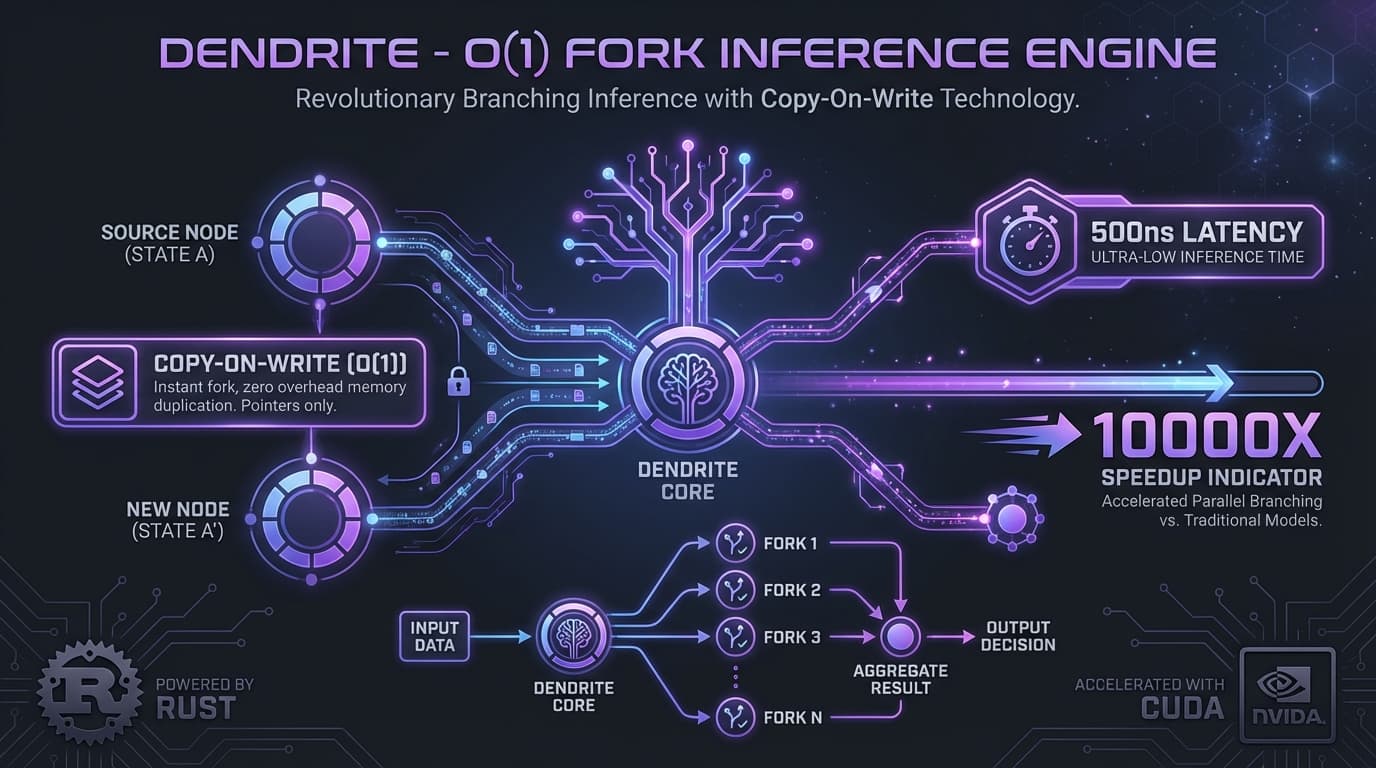
Dendrite implements copy-on-write KV cache at the page level. Forking becomes a metadata operation: just incrementing reference counts. The actual memory copy only happens when a forked branch modifies a page.
Performance
- Fork latency: 500 nanoseconds (vs milliseconds in vLLM)
- Memory efficiency: 10-100x reduction in fork memory overhead
- Throughput: 1000-10000x faster branching operations
Technical Stack
- Core engine in Rust for memory safety and performance
- CUDA kernels via FlashInfer for attention computation
- Candle for tensor operations
- Custom PagedAttention implementation with CoW semantics
Use Cases
- Monte Carlo Tree Search for complex reasoning
- Speculative decoding with multiple draft models
- Beam search with aggressive pruning
- Agent backtracking and state restoration
Why This Matters
As AI agents become more sophisticated, they need to reason about multiple futures simultaneously. Dendrite makes this computationally tractable.
Connected work