What it is
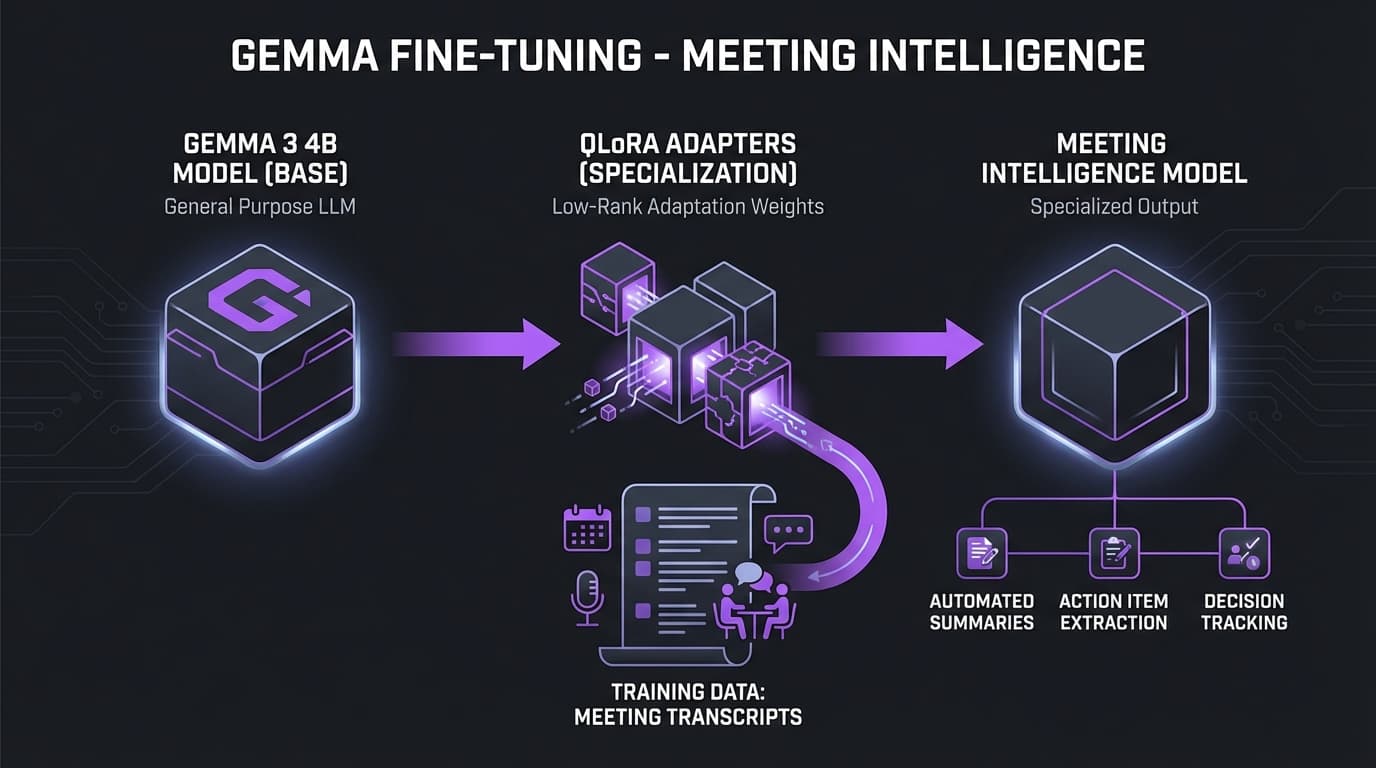
Gemma Fine-tuning explores whether small, specialized models can outperform larger general models on specific enterprise tasks, in this case, meeting intelligence.
The Hypothesis
A 4B parameter model fine-tuned on meeting transcripts should outperform larger general models at tasks like summarization, action item extraction, and follow-up generation. Domain expertise beats raw scale.
Training Approach
- Base Model: Gemma 3 4B (Google's efficient open model)
- Method: QLoRA (Quantized Low-Rank Adaptation) for memory efficiency
- Frameworks: TRL and Axolotl for training orchestration
- Hardware: DGX Spark's 128GB VRAM enables full-batch training
Training Data
- Anonymized meeting transcripts
- Human-annotated summaries and action items
- Structured output examples for consistent formatting
Integration with Axon
The fine-tuned model powers Axon's meeting intelligence features:
- Real-time transcript summarization
- Action item extraction with assignees
- Follow-up email generation
- Meeting prep synthesis
Why Gemma
Gemma 3 offers an excellent balance of capability and efficiency. At 4B parameters, it runs fast enough for real-time applications while being small enough to fine-tune on personal hardware.
Results
The fine-tuned model shows significant improvements over base Gemma on meeting-specific tasks, validating the hypothesis that specialized training beats general capability for narrow domains.
Connected work